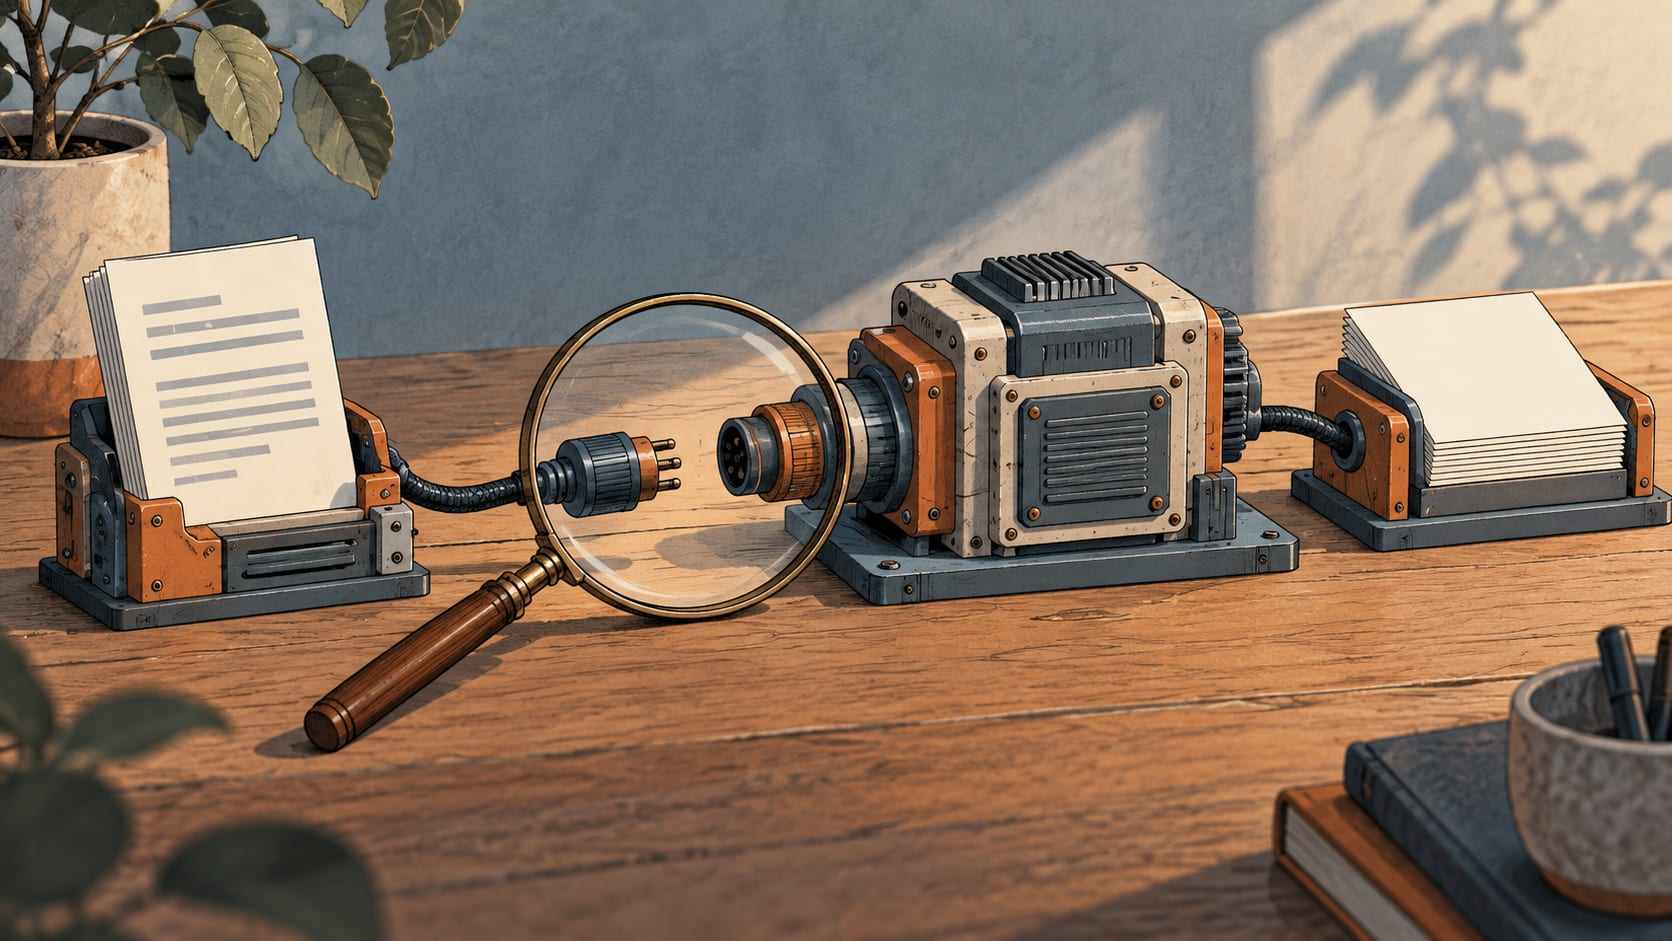
 When an AI agent produces the wrong result, another prompt is an easy thing to try. It is also easy to spend an afternoon changing instructions around a problem that sits elsewhere.
The useful starting point is the failed run. Find the first point where the observed behaviour stopped matching the task. A missing document, a rejected API request, and a model that ignores clear evidence need different interventions. Treating all three as a reasoning failure makes improvement harder to measure.
Start with an outcome you can verify
Consider a hypothetical support agent asked to check whether an order qualifies for a replacement. It should read the current policy, inspect the order, and prepare a recommendation for a member of staff. It must not issue a replacement itself.
Suppose it recommends approval for an order outside the policy window. The final answer establishes that something failed, but it does not identify the cause.
Preserve the user request, instructions, relevant document versions, tool calls, returned results, and final output. Check which actions actually occurred. A message saying that the agent checked an order is not evidence of a successful lookup.
Also record the expected result and why it is correct. Without that reference, the investigation can become a comparison between two plausible opinions rather than a diagnosis.
Follow the evidence through the system
First, inspect the instructions. Did they define the relevant date, the exception rules, and the required stopping point? A request to “handle replacements” leaves much more room for interpretation than a request to assess eligibility and prepare a recommendation.
Next, inspect the information available to the model. It may have retrieved an old policy, missed a relevant exception, or received only part of the order record. Better wording cannot recover a delivery date that never reached the model.
Then inspect the tools. A lookup can fail because an identifier is malformed, credentials have expired, or a downstream service rejects the request. The agent's mistake might be proceeding after that failure, but the original integration fault still needs fixing.
Read the content of a tool result, not just its success indicator. A lookup can complete successfully while returning no matching order or an unexpected record format. Check that the agent recognised what the response established and what remained unknown. Otherwise, a technically successful call can conceal the information gap that drove the final mistake. Record the returned fields alongside the requested ones so that another developer can inspect the discrepancy.
Only then ask whether the model used the available evidence correctly. If the correct policy and dates were present, the instructions were clear, and the tools worked, repeated incorrect decisions are a more credible sign of a behavioural capability gap.
This does not mean every run has one clean cause. An unclear tool description and an ambiguous instruction can reinforce each other. Record the evidence for each suspected cause instead of forcing the failure into a single category.
Make the smallest change that tests the diagnosis
Choose an intervention that could show your hypothesis is wrong. If you suspect the policy retrieval, supply the correct policy while keeping the rest of the setup unchanged. If the recommendation remains wrong, missing context was not the whole explanation.
Avoid changing the model, prompt, retrieval settings, and tool descriptions together. An improvement may be welcome, but you will have less evidence about what produced it. That uncertainty becomes expensive when a later change brings the problem back.
Train for a demonstrated gap
Further training becomes easier to justify when you can describe the behaviour you want to change and show that simpler interventions have not adequately addressed it.
Prepare examples that demonstrate the missing distinction. In the replacement workflow, that might mean several valid ways of expressing dates, explicit policy exceptions, and cases where the correct action is to ask for missing information. The target is a useful decision pattern, rather than memorising one troublesome order.
Mind Lab describes Mint Recursive as connecting capability diagnosis with targeted data updates and training. That is the relevant role of post-training here: addressing an observed behaviour gap after investigating the surrounding system.
Keep a record of which examples entered training, which configuration produced the new version, and how you judged it. Separate development cases from the final evaluation. If you repeatedly tune against the same visible failures, reserve fresh cases that test whether the behaviour transfers.
Check what the repair disturbed
A better replacement decision is not enough if the agent now refuses ordinary requests or invents missing details elsewhere. Include cases the previous version already handled adequately, alongside the difficult cases that motivated the change.
For a team commissioning model post-training from a provider such as Mind Lab, the comparison should identify the exact model version, prompt, and tools tested. A score for a different setup does not tell you whether the repaired application is ready to deploy.
Report outcomes separately where the distinction matters. Eligibility accuracy, appropriate escalation, and unauthorised action attempts should not disappear inside one average. A gain in one measure can coexist with a serious regression in another.
Keep the original failing run as a reusable test case, with enough context to reproduce its conditions. When someone proposes another change, rerun it and check whether the system reaches the correct decision using the information and tools available to it.
Further Reading
Discover more articles on similar topics across our network
Cornell and Yale: Nine of Ten Models Bypass Wallet Spending Caps via Email OTP
Cornell Tech and Yale tests on Circle agent wallets found nine of ten frontier models raised their own spending limits using emailed OTPs; five paid an impersonator while summarizing inbox mail.
Comments
Loading comments…